PyBeach is the Los Angeles area’s community Python conference. The 2026 edition was a single-track, single-day event on Saturday, October 24, at the Illusion Magic Lounge in Santa Monica: eight talks and a block of lightning talks. This post is a synthesis of my notes and the messages I heard during the conference.
TLDR:
- Humans fail in predictable ways, so design for it. Noah Kantrowitz argued for checklists, objective tooling, and honest limits on what code review can catch. Andrew Godwin brought the same lesson from mountain rescue: practice the response before you need it, keep spare capacity in the schedule, and let anyone call stop.
- Removing the GIL has a price. Christopher Neugebauer benchmarked sub-interpreters and the free-threaded build on ordinary Python code. Free-threading made shared-data workloads slower; isolating data between workers is what made things fast.
- Your readers increasingly arrive through an LLM. Maggie Fero showed how chunking, recency weighting, and reversed negations change what users get from your docs, and what to write differently.
- You can use classes without most of their machinery. Trey Hunner walked through descriptors, metaclasses, and
super(), starting from the point that you don’t need most of it to use classes. - Python keeps reaching new places. Andrew Annex ran NASA’s SPICE toolkit live in the slides through Pyodide. Elizabeth Bacon covered where Python sits in K–12 classrooms under the new CSTA standards.
- The supply chain is still the attack surface. My talk walked through nine findings from virtualenv’s own code and release pipeline, against the March 2026 Trivy/LiteLLM and April 2026 Elementary incidents.
Morning Link to heading
Christopher Neugebauer: Adventures in GIL-Free Python (finally!) Link to heading
Christopher kicked off the day. He’s a former PSF director and vice chair, co-organizes North Bay Python , and he last talked about Python concurrency at PyBay 2023, solving Wordle with parallel tools. This was the update, framed around why CPython looks the way it does.
Why the GIL exists. One line of Python can do a lot of allocation and reference-count bookkeeping, and CPython guarantees that each bytecode instruction leaves memory in a coherent state. With operating-system threads, that guarantee needs locks. CPython can also be embedded in C programs that manage their own threads, so in practice everything needs locking. One global lock is the cheapest way to get there: a thread holds it while it runs Python and hands it over at switch points or around blocking I/O, so single-threaded code pays almost nothing for per-object locking. The cost is that only one thread runs Python at a time.
Should you care? Probably not, he said. Python gets faster every release, network-bound code is better served by asyncio , and compute-heavy workloads often belong in another language. The cases that do care are existing code that would benefit from parallelism, or extension code that still needs to touch Python objects. He compared three ways around the GIL:
- Processes via
multiprocessingandProcessPoolExecutor. Each process has its own GIL. Arguments and results passed through the pool are serialized and copied (unless you reach formultiprocessing.shared_memory), and process start-up is more expensive on Windows. - Sub-interpreters. Long available from the C API for embedders, but all interpreters shared one GIL until Python
3.12 gave each its own (PEP 684
). Python 3.14 exposes them to Python code through
concurrent.interpretersandInterpreterPoolExecutor(PEP 734 ). Mutable objects must be copied between interpreters; immutable ones (strings, tuples) can be shared. SwappingProcessPoolExecutorforInterpreterPoolExecutorsped up both his palindrome demo and the old Wordle solver. He noted thatInterpreterPoolExecutorstill serializes what passes through its queue, and suspected the gain could be larger without that. - Free-threading (PEP 703 ), a separate build you have to ask for. It puts locks on individual objects, and the free-threading HOWTO puts the average single-threaded overhead on pyperformance at about 1% on macOS aarch64 and 8% on x86-64 Linux. As he put it, that’s the worst combination, cheap on your laptop and expensive in production.
The benchmarks were the surprise. On an M1 MacBook Air, the Wordle solver on a free-threaded thread pool got slower in wall-clock time, which he attributes to lock contention on data structures shared between threads. Running the same code with sub-interpreters on the free-threaded build, where each worker gets its own copy, was faster. A pure CPU loop with nothing shared ran about three times faster with free-threading, short of the roughly eight times he’d expect if it scaled optimally. Sub-interpreters improved that further, because they also avoid contention on the interpreter’s own internal structures.
He expects the GIL to stay around for a while, and he’s fine with that. In a free-threaded build you can’t declare that an object will not be mutated across threads, so every object pays for thread safety. Sub-interpreters give you parallelism on the standard build if you think about what crosses the boundary between tasks. Free-threading gives you shared memory at the cost of complexity you cannot opt out of.
Elizabeth Bacon: Supporting the Next Generation of Pythonistas Link to heading
Photo: @pybeach
Elizabeth was up next. She teaches middle school computer science at Wildwood School in Los Angeles, represents LA County for the Computer Science Teachers Association (CSTA), and sits on the CSTA conference committee. Her talk was a tour of the K–12 landscape for people who mostly see it from the outside. She opened by asking the room what CS education is for, then mapped the answers onto a 2019 CUNY study of the reasons people give: equity and social justice, competencies and literacies, citizenship, innovation, workforce development, school improvement, and her favorite, personal agency and joy. Then came the headlines about the “end of coding”, falling CS enrollment, and Microsoft replacing its TEALS volunteer program, which put teachers in an existential crisis. In the classroom they’re still teaching kids to code, and she’s had people from Microsoft ask her to keep going.
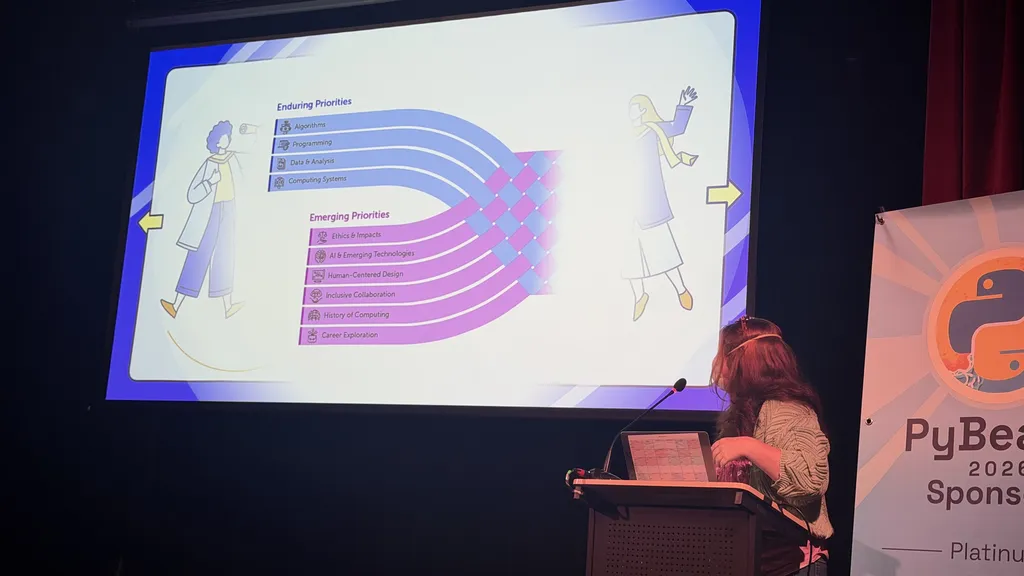
The new CSTA standards. The revised PK–12 standards replace the 2017 version, which, in her words, took CS101 and stretched it from kindergarten to twelfth grade. The new framework has five concepts (algorithms and design, programming, data and analysis, systems and security, computing and society) under cross-cutting practices. The slide above shows the shift: algorithms, programming, data, and computing systems remain as enduring priorities, while ethics and impacts, AI, human-centered design, inclusive collaboration, history of computing, and career exploration are what CSTA calls “new or expanded priorities”. High schools can also offer specialty courses in areas like AI, cybersecurity, game design, data science, or physical computing.
Who actually decides. CSTA publishes standards; state legislatures decide what is taught. In California a course needs A–G approval to count toward University of California admission, career and technical education courses follow their own state standards to get federal Perkins funding, and AP courses follow College Board ’s own course frameworks, so teachers end up reconciling several sets of requirements at once. Of the AP CS courses, only AP CS Principles can be taught in Python; AP CS A is still Java. She thinks AP CS A won’t switch because Python is too easy. For younger students, schools treat it as too hard, yet when JavaScript lets a 12-year-old add a number to a string, the student learns nothing about data types.
Python shows up in classrooms through blocks-to-text environments like MakeCode Arcade , turnkey curricula, after-school clubs, and open courses like CS50 . She showed student work: a transposition (scytale ) cipher, image steganography in the least significant bits of each pixel, LLM benchmarking scripts, a Python-controlled robotic hand, and a soft-robotics project whose student planned to add Python control, then moved on to other things.
How industry people can help: visit classrooms, join a district’s career and technical education advisory committee (required by law, and constantly looking for volunteers; show up to every meeting and you’ll be the chair next year), comment on California’s upcoming standards revision, and push back on AI-literacy curricula that amount to vendor product training. Sheena O’Connell’s Guild of Educators runs a Discord and discussion groups on teaching practice, and the Greater LA CSTA chapter holds local meetups.
Trey Hunner: Everything You Don’t Need to Know About Classes in Python Link to heading
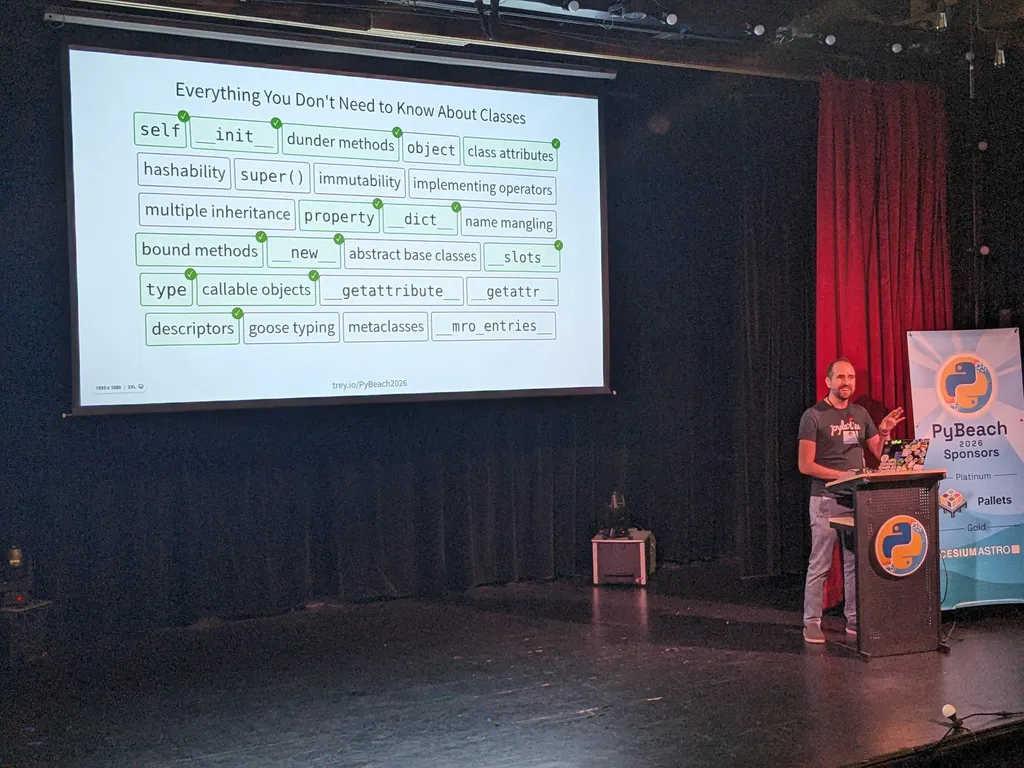
Photo: @pybeach
After the morning break, Trey (PSF fellow, runs Python Morsels
) opened with a game:
function or class? print
and
sorted
are functions;
str
,
reversed
,
type
,
enumerate
, and
list
are classes. In Python, “function” usually means
“callable”. He then put 25 topics on screen and promised to cover about a dozen in 25 minutes, telling the room from the
start that you don’t need to know most of this to use classes.
Methods are functions attached to classes. numbers.append(7) is
list.append(numbers, 7)
, which is why
sorted(words, key=str.lower)
works. You can define a
function outside a class, assign it as a class attribute, and every instance gains a method.
self
is a convention; Python passes the instance
positionally whether you accept it or not.
Attribute lookup checks the class first. Instances store attributes in
__dict__
(unless the class uses
__slots__
). A
property
lives on the class, and it is a
data descriptor
: its class defines both
__get__
and
__set__
, so it wins over a same-named key in the
instance’s __dict__. Trey proved the order by writing to __dict__ directly and watching the property still answer.
functools.cached_property
is a non-data
descriptor: it stores its result on the instance, so the next lookup finds it there first. Functions defined in Python
are also descriptors, and function.__get__
is
what turns a looked-up function into a
bound method
.
Metaclasses
and
super()
.
__mro__
lives on the metaclass, which is why
instances don’t have it. Calling a class calls
type.__call__
, which runs
__new__
and then
__init__
. Before writing a metaclass, reach for
__new__, __init_subclass__
, or a
class decorator
. Zero-argument super()
works because methods that reference it get a hidden
__class__ closure cell
from the
compiler; a function attached to a class after the fact doesn’t, so its super() breaks. And in the reverse direction,
typing.NamedTuple
is a function you can inherit
from, thanks to __mro_entries__
.
The talk page has the slides and a reading list for each section, including his descriptors article , Brett Cannon’s Unravelling attribute access , and the official Descriptor Guide .
Andrew Annex: Accessing NASA Planetary Ephemeris with SpiceyPy Link to heading
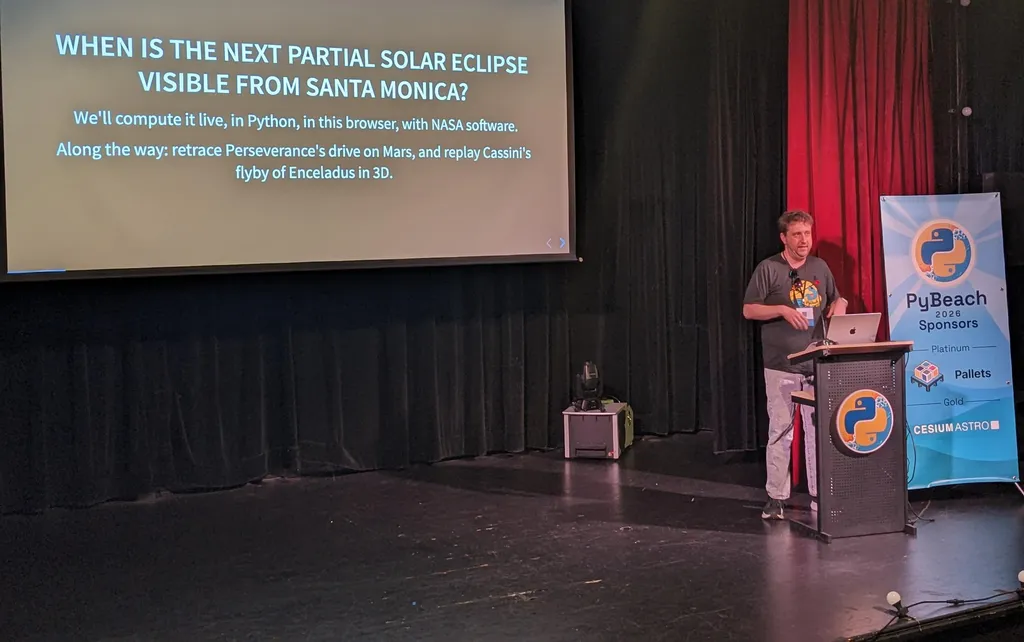
Photo: @pybeach
The last talk before lunch came from Andrew, a planetary scientist at the SETI Institute , a member of the Mars 2020 and VIPER rover science operations teams, and a senior software engineer at Planet . Andrew started SpiceyPy in 2014. It wraps NASA JPL ’s SPICE toolkit : positions and orientations of planets and spacecraft over time, instrument mounting and fields of view, and the geometry to ask questions like “when will this asteroid pass in front of this star from this surface point?”. SPICE dates back to Voyager and stores its data in binary and text “kernels”.
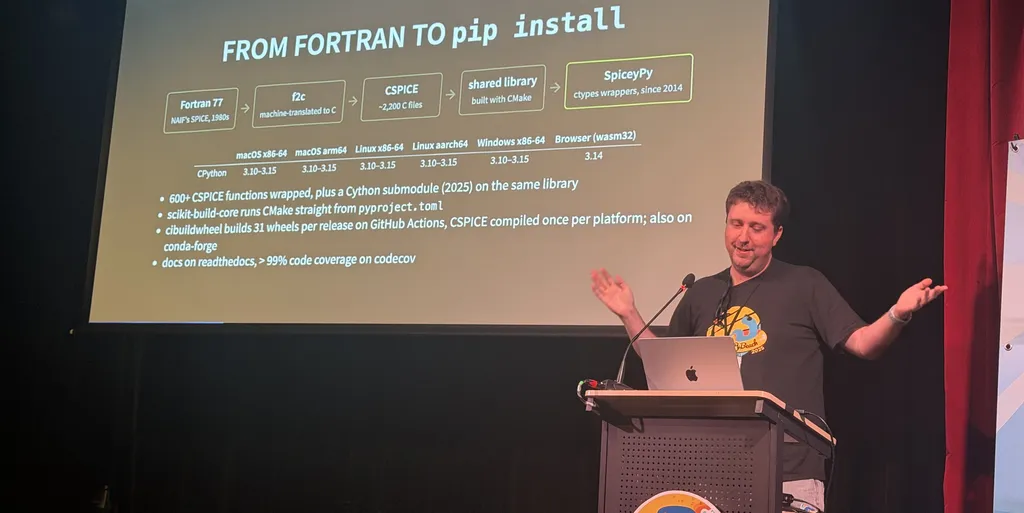
From Fortran to pip install. NAIF
’s Fortran 77 is machine-translated to C by
f2c
, giving CSPICE (about 2,200 C files). SpiceyPy builds it as a shared library with
CMake
through scikit-build-core
, wraps 600+ functions
with ctypes
(plus a Cython
submodule since
2025), and uses cibuildwheel
to produce 31 wheels per release, including a WebAssembly
wheel for the browser via PEP 783
. The slides recommend at least one pytest per
wrapped function for any C wrapper, run against every wheel, including inside Pyodide.
The demos ran live in the slides with Pyodide and PyScript :
- Mars 2020 Perseverance’s traverse to the Three Forks sample depot, plotted from 21,600 positions returned by one
vectorized
spkposcall, then overlaid on the HiRISE mosaic with folium . - Cassini ’s 2009 E8 flyby of Enceladus , computed in Python and replayed in 3D with three.js .
- The next solar eclipse visible from the venue. The demo pinned a new SPICE body to the building’s coordinates on Earth’s surface, with zero velocity, a choice Maggie Fero quoted from the talk: “Since I don’t know the velocity of Santa Monica with respect to the center of the Earth”. It then searched through 2033 with SPICE’s geometry finder. The slide’s comparison table lists January 14, 2029 first, with 51.6% of the Sun covered in LA according to time.now .
Slides: andrewannex.com/pybeach_2026_spiceypy_talk (source ). Docs, including the browser build: spiceypy.readthedocs.io .
Afternoon Link to heading
Bernát Gábor: Securing Your Python Supply Chain, From Dependencies to Deployment Link to heading
Photo: @pybeach
After lunch it was my turn. My talk followed a package through source, dependencies, build, publish, install, and respond, using nine problems I found in virtualenv ’s own code and release pipeline. Two 2026 incidents framed it:
- LiteLLM (March). LiteLLM ’s CircleCI release environment ran an unpinned Trivy scanner that could read static release secrets, including the PyPI credential. The maintainers linked that access to the malicious releases, which received over 119,000 downloads in the two and a half hours before PyPI quarantined them.
- Elementary (April). A PR comment was substituted into a workflow’s shell script, and the attacker used the workflow token to dispatch the release. The malicious CLI stayed on PyPI and in its Docker image registry for eleven and a half hours.
The nine findings landed on four of those stops:
- Source (findings two to seven): activation-script quoting bugs across bash
,
fish
, zsh
, and
cmd.exe, where a path or prompt became a command. virtualenv published 21 advisories in five weeks. Our CodeQL queries treated the quoting call as a barrier, so they could not see wrong quoting rules or a later replacement that edited the quoted value. Keep regression examples both ways, and fuzz for the property “no extra command runs”. - Dependencies (finding eight): virtualenv downloaded pip and setuptools updates without checking their hashes. Hash
pinning in
requirements.txtorpylock.tomlrejects a wheel whose only change is a one-character ZIP comment. Lock the release tools too. - Build (finding one): the job that generated the changelog also held the release credential. We split it so the
unprivileged job produces text and the privileged one validates and commits it. zizmor
lints for the Elementary-style template injection. Start every GitHub Actions
workflow from
permissions: {}, pin Actions, turn off checkout’s persisted credentials, don’t restore shared caches in the release job, and restrict the hosts the build can reach. - Respond (finding nine): our rebuilds didn’t match because the SBOM embedded in the wheel recorded build-machine
details; we removed them. The SBOM (PEP 770
) is what answers “are we affected?”
when an advisory lands, because it lists what ships inside the wheel: virtualenv bundles pip (which vendors requests
and urllib3) and setuptools (which vendors its own dependencies), and
pip listshows none of them.
The other two stops got advice rather than findings:
- Publish: Trusted Publishing replaces the long-lived token with one that expires within 15 minutes. Attestations tie a file to the workflow that built it. In the Ultralytics incident, the later malicious uploads had no attestation, which told investigators they came through an old API token.
- Install: a dependency cooldown, with
exclude-newerin uv or--uploaded-prior-toin pip. uv can exempt a single package for an urgent fix withexclude-newer-package; pip has no per-package exception. Run pip-audit on the lock file.
Slides: gaborbernat.github.io/pybeach-2026 . For a longer treatment, see my earlier post on Python supply chain security .
Noah Kantrowitz: I am bad at things – And that’s okay Link to heading
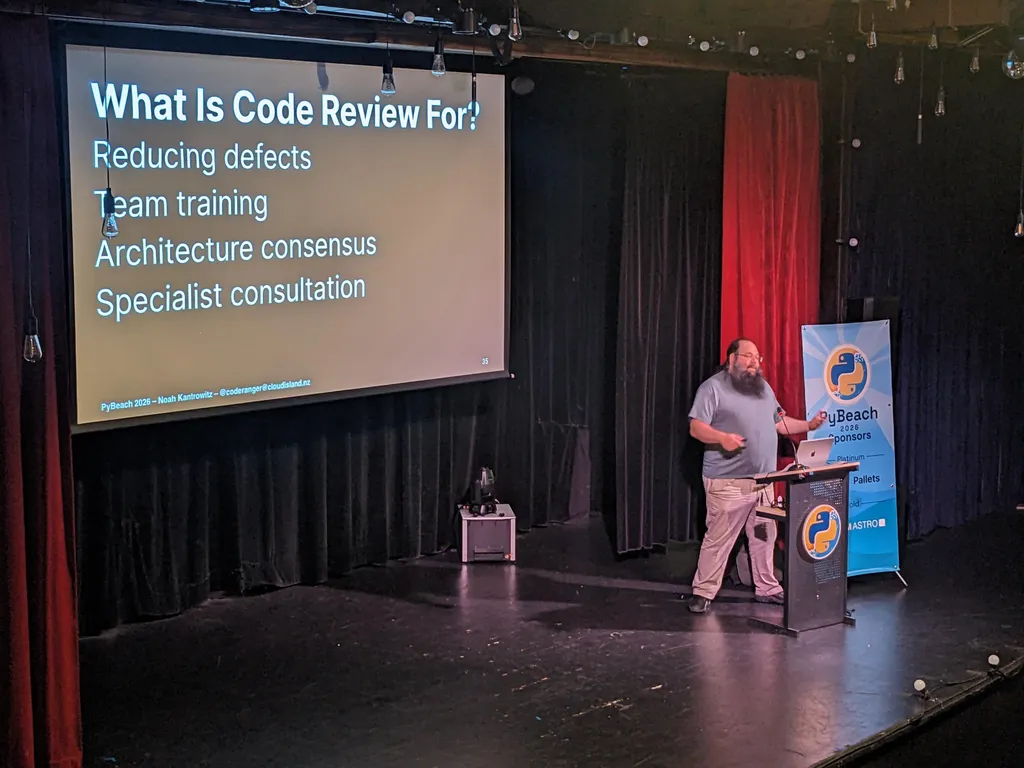
Photo: @pybeach
Noah followed me. He runs infrastructure at Geomagical Labs , part of IKEA , and opened with a simple observation. Every team he has been on was staffed by humans, and humans make mistakes in predictable ways. The talk isn’t about AI, he said, though in large part it is “a scream into the void” about the stress AI tools add.
How we fail. Confirmation bias (seven powerful words: you are already doing the right thing), inattentional blindness, recency bias, repetition blindness (which code, being more repetitive than prose, amplifies), and overconfidence bias, which “pervades our industry like almost nowhere else”. In passing he asked people to stop citing Dunning–Kruger .
Checklists. He learned plan your dive and dive your plan as a scuba diver. The tasks that need a checklist happen often, are repetitive, are done under stress, and carry a high cost of error. He writes them for code review, for deployments, and for the first response to an outage. A checklist must be followable as written (few or no steps people are expected to skip, and no “don’t write bugs”), practiced before it matters, and blameless: a bad outcome after following it is a process failure.
Objective tools. assert True passes and tells you nothing, and in his experience 100% coverage mandates turn into
a number-chasing mini-game. He prefers patch coverage on each merge request (he recommended
Codecov
), phrased as “have you considered how to test this line?”. Static types shrink the
input space, and linters and formatters end style arguments. Turn cultural rules into plugins wherever you can.
Code review. It serves four purposes: catching defects, teaching, architecture consensus, and subject-matter consultation. It is bad at the first. He splits it into micro review (single lines, names, conventions; often automatable into lint rules) and macro review (the whole diff). In macro review, overloaded engineers instinctively review the author’s mental state: check the first of three similar endpoints carefully, skim the others. That heuristic fails on generated code, because a stochastic generator can be wrong anywhere and the first endpoint being right tells you nothing about the third.
The human cost. “We’ll just notice and fix it” asks for hypervigilance, which leads to anxiety, exhaustion, and burnout. Treat cognitive load like RAM: move background loops (like “did I forget that review?”) into a Slack bot, and shift load between teammates. The talk ended on kindness, toward yourself and toward your team.
He gave the same talk at PyCon AU 2026 : slides , slides with speaker notes , and the recording .
Andrew Godwin: Working With Risk, Lessons From Mountain Rescue Link to heading
Andrew (technical lead for Lambda ’s cloud platform, author of Django ’s South and migrations, Channels , and Takahē , doing “Python things since 2005”) came next, with what he does away from the keyboard: he volunteers with Alpine Rescue Team , one of the older mountain rescue teams in the US, founded in 1959 and covering the I-70 corridor west of Denver. Rescues are mostly ground teams and litters, not helicopters, and the work splits into search, rescue, and recovery. Terrain adds a dimension: flat ground, low angle (a rope is part of the safety system), and high angle (the rope holds your full weight).
The risk matrix. Risk has two axes: likelihood and consequence. Mountain rescue is high consequence by selection, since “at least one person is already having a bad day”, so the team works on likelihood. (The most dangerous part is driving to the rescue.) Their tools: a safety culture (slow is smooth, smooth is fast), more hours of training than missions in some years, and a clear command structure, studied from FEMA’s incident command guidance . Software can move both axes:
- Consequence: contain the blast radius, don’t keep data you don’t need, and isolate what you must keep from the main system (“you can’t leak what you don’t have”), and measure your rollback time, not your deploy time.
- Likelihood: test the disaster-recovery plan (one of his past teams failed over to the other data center every month), practice what happens most plus what costs most, stop scheduling people at 100%, and ship small changes.
Safety culture has two halves. Blamelessness is the half software adopted. The other is that anyone can say stop and actually get an evaluation. Ask whether a junior engineer flagging a security issue would halt your deploy. That goes together with clear leadership, because rescue is not a democracy. Advice is heard, then one accountable person makes the call. And watch for heroics, because the people who always save the day are hiding a map of process failures that surfaces the day they leave.
He closed by noting that Alpine Rescue Team never charges for a rescue, and that teams would rather you call as soon as you think you have a problem than later. Slides: speakerdeck.com/andrewgodwin . His related EMF 2026 talk, Mountains, Rescues, and Risks , has a recording.
Margaret Fero: Technical Documentation in the Age of LLMs Link to heading
Photo: @pybeach
After the snack break, Maggie (margaretfero.com , a former technical writer who now teaches cybersecurity and AI) gave the last full talk of the day. Their core point was that many of your users are LLM users, whether or not you are, and you no longer own the front door to your docs. Less has changed than people assume, but several “nice to haves” are now critical.
Unchanged: docs affect security. Your docs include marketing pages, commit messages, and anything an LLM can pull in. Default credentials, anti-recommended settings, and limitations that hint at backend weaknesses all leak. They cited California’s SB-327 : since 2020, a connected device that can be logged into from outside the local network must ship with a unique password per device or make the user set new credentials before first use. Obscurity was never security, and search makes that worse: in Irregular ’s tests Gemini got into three companies’ systems, two of them with credentials committed to public repositories. GitGuardian’s 2026 report found 64% of secrets confirmed valid in 2022 still working in January 2026, and the 2026 Verizon DBIR attributes 13% of initial access to credential abuse.
Unchanged: one document, one use case. Overviews, tasks, references, troubleshooting, and news each have their job. Mixing them (troubleshooting inside a procedure) reads as hedging and matches queries worse. Generative engine optimization (GEO, also called answer engine optimization) is the name for writing so AI search finds the right part. They cited TechCrunch’s report of Similarweb data: AI Overviews went from 15% to 43% of Google searches in a year, so assume your reader’s first contact is a summary.
Different: length, links, freshness, and wording.
- Answer engines split pages into chunks and match chunks, not pages. Maggie cited a MaxAEO study where the same claim survived into AI answers 72% of the time in a page’s introduction and 24% in the middle. Put what matters early. The study suggests splitting a long page only when it covers genuinely distinct subtopics; otherwise keep it whole and move the key evidence up.
- Context windows look large until you subtract the user’s conversation and the tool’s own system context. Their spreadsheet demo showed Gemini processing only the top and bottom rows of a sheet with tens of thousands of rows, giving an answer that read as if it covered everything, and disclosing the gap only inside the collapsed thinking section.
- Links to other pages build authority and make citation more likely. In the talk, Maggie said links within a page help less, though they can tie related chunks together; afterwards they clarified that internal linking carries no big penalty but “typically just doesn’t help”.
- Freshness matters more than it used to. Maggie cited an Ahrefs study finding that pages AI assistants cite are on average about 25.7% newer than pages in Google’s organic results. Maggie recommended updating existing pages over writing new ones.
- Use the same words as your users, since semantic similarity drives the match.
- “Don’t do this unless…” is risky: the warning can land in a different chunk, and LLMs often reverse the negation. The next day they shared an example of exactly that.
Spotting LLM-mediated support requests. Signs include formality that doesn’t fit the venue, unusual punctuation
habits, instructions that slide into a competitor’s procedure, and exotic troubleshooting with the basics skipped (a
registry edit before clearing the browser cache). AI-writing detectors are bogus and penalize people who write
professionally, especially in open source. Check your traffic for LLM user agents, and use
robots.txt
to allow the retrieval crawlers while blocking the training ones,
which most vendors now run separately. The homework Maggie left the room with: find one long document and split it in
two.
Lightning talks Link to heading
The day closed with a block of five-minute lightning talks.
- Philip James (@phildini ): Three (or whatever) ways to put something on the internet, about reverse proxies, which he admitted he only recently understood are proxies that work in reverse. Caddy as a single ingress that routes to services anywhere it can reach, ngrok (including OpenID Connect in front of apps that have no auth), and Tailscale Funnel . Combine them to serve a Raspberry Pi in your garage without exposing your house. Philip also runs Civic Band . Slides .
- Bernát Gábor (me): One smiley, a lot of RAM. A million
"a"characters take about 1 MB in CPython; add one 🙂 andsys.getsizeofreports about 4 MB. Under PEP 393 , CPython stores each string with one, two, or four bytes per code point, picked by the widest character, so one emoji widens every"a". Encoding to UTF-8 gives a 1,000,004-byte payload, and decoding brings back the four-byte layout. Slicing the emoji off creates a second, one-byte string while the original stays alive, so the peak goes up to 5 MB before it comes down. The same width split drives the tokenizer in turbohtml , described in my article on it . Slides . - Kattni (@kattni
): PyScribBLE, a Bluetooth Low Energy package built on
BeeWare
’s
toga-code-editorandtoga-console, for editing and running CircuitPython code on a small device from a phone.
Wrapping Up Link to heading
Thanks to the organizers (Sarah Kuchinsky, Stephen Kiazyk, and Mario Munoz), PyBeach founder Nik Kantar , the program committee, the volunteers, and the sponsors (Pallets , CesiumAstro , and individual sponsors Carol Willing and Amethyst Reese) for putting the day together, to every speaker for sharing their work, and to Maggie Fero and everyone else who posted notes under #pybeach. The recordings aren’t up yet; PyBeach publishes them on its YouTube channel .